“Excluded by noindex tag” means Google recorded an instruction to keep that URL out of search. First decide whether that instruction is intentional. A checkout page and a public service page can have the same report status while needing opposite decisions.

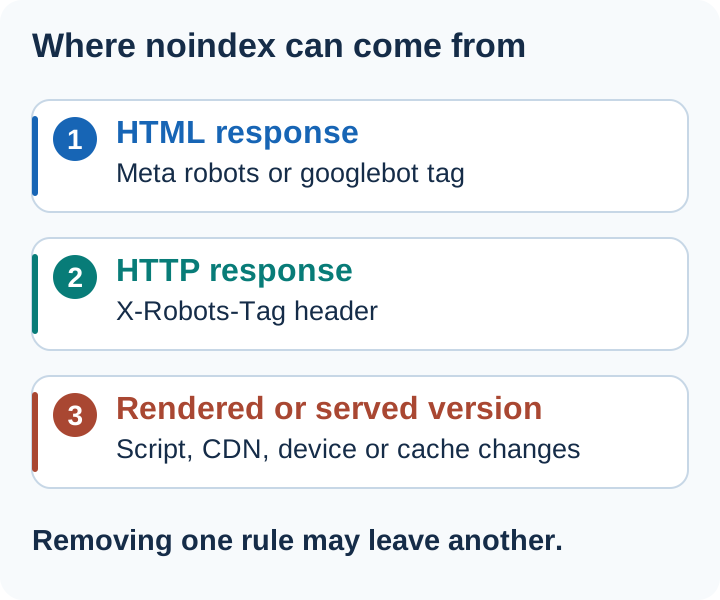
If the page should be eligible for search, find where the noindex is delivered before changing settings. It can come from HTML, a response header, a CMS option, a plugin, a template or the delivery layer. Removing one visible tag may leave another applicable rule in place.
Decide which pages should stay excluded
Use the exact affected URL, not only its page title. A service page, a preview copy and a printer version may look similar but have different purposes.
| URL purpose | Sensible first decision |
|---|---|
| Public service page, product or substantive article you want found | Investigate an accidental noindex |
| Thank-you or transaction utility page | Keep the deliberate exclusion if it still matches the page’s purpose |
| Preview or staging copy | Keep it out of search; review actual access protection separately |
| Internal search or a low-value filter pattern | Review the intended search policy before changing a whole template |
| Duplicate of a preferred public page | Decide whether canonical consolidation is more appropriate than exclusion |
| Confidential content | Use access control; noindex does not restrict who can open the URL |
Do not remove every noindex from a shop or a staging environment to reduce the excluded count. Define the intended indexing policy for the affected page type.
Google’s noindex documentation explains both implementation methods and the need for Google to crawl the resource to read the instruction.
Record the old state before checking the live page
In Search Console’s URL Inspection, save the indexed result’s:
- exact URL and reported exclusion;
- Last crawl and inspection date;
- Crawl allowed?, Page fetch and Indexing allowed? values;
- any recent release date or relevant CMS change.
If Google last crawled before you removed noindex, the older state is not evidence that the fix failed. If the crawl happened after your release, check whether a cache, a second rule or a different response still supplied the instruction.
URL Inspection’s indexed and live views describe different observations. A successful live test can help confirm current availability; it does not itself add the page to the index.
Check all three delivery locations
1. HTML robots meta tags
Open the public page’s source and search for robots-related meta tags. These illustrative examples exclude a page from Google Search:
<meta name="robots" content="noindex">
<meta name="googlebot" content="noindex">
none is also significant: Google defines it as equivalent to noindex, nofollow. The rule may be combined with other values, so searching only for one exact tag string can miss it.
Read every applicable tag. A generic index value alongside a Googlebot-specific noindex does not make the page eligible for Google indexing.
2. HTTP response headers
A page can contain no noindex meta tag and still send:
X-Robots-Tag: noindexOr the instruction may be scoped:
X-Robots-Tag: googlebot: noindexCheck response headers in the browser’s Network panel or capture a GET response. Inspect the final document response when redirects are involved, while keeping a record of the redirect path.
Headers also work for resources such as PDFs, where an HTML meta tag is not the relevant mechanism. Check a missing PDF’s own response rather than only the page that links to it.
Google’s robots directive specification explains crawler scopes and conflicting rules. An additional permissive instruction does not override an applicable restrictive one. Remove the accidental rule at its source.
3. Rendered or delivery-dependent output
Initial source, the rendered page and a cached response can differ. Compare the returned HTML with View tested page in Google’s live test when JavaScript or delivery rules might affect the result.
Our Google Index Checker reads public response HTML and headers, including generic and Googlebot-specific directives. It does not execute JavaScript, inspect your CMS settings or query Google’s index. Its result tells you what that particular public fetch could test.
If it finds no noindex, that is a reason to compare dates and response variants, not proof that Google never saw one.
How to fix Excluded by noindex tag: trace the rule to its source
Use the pattern of affected URLs to narrow the search:
| Pattern | Where to investigate |
|---|---|
| Most public pages changed after launch | Site visibility setting, environment configuration or global response rule |
| One page only | Its per-page SEO setting, template override or custom field |
| One post type or archive family | A post-type, taxonomy or template-level indexing policy |
| HTML looks correct but every response has the header | Web server, hosting control panel, CDN or application middleware |
| Only a PDF or another file type is affected | File delivery and file-type header rules |
| Public checks disagree at different times | Cached output, deployment state or conditional delivery |
Save the relevant response, then trace the matching rule before disabling a plugin or removing a global setting.
WordPress, Yoast and Rank Math: check site visibility and narrower settings
In WordPress, review Settings → Reading → Search Engine Visibility. The official Reading settings documentation describes the option labelled “Discourage search engines from indexing this site.” It is an indexing preference, not password protection.
For a public production site, correct an accidentally enabled site-wide preference. Then check any SEO plugin’s page-level and content-type settings, plus response headers, for another applicable noindex:
- Yoast SEO: in the post editor, the Yoast Advanced tab asks “Allow search engines to show this content in search results?”. A whole content type is switched off under Yoast SEO → Settings → Content types.
- Rank Math: the post’s Advanced tab has a Robots Meta section with a No Index box (it appears once Advanced Mode is on). Rank Math SEO → Titles & Meta sets the default robots meta for each post type, and a post-level setting overrides it.
Make a focused change and verify what a signed-out visitor receives. A dashboard checkbox is configuration evidence; the public HTML and headers show the resulting output. Clear the relevant page or CDN cache if it is still serving the old instruction, then retest.
Squarespace, HubSpot and Shopify
| Platform | Where a page-level noindex is set |
|---|---|
| Squarespace | Pages panel, the page’s settings, SEO tab, Hide page from search results; or a robots meta tag in the page header code injection (not on Basic or Personal plans). Hiding a blog or store page also hides its items. |
| HubSpot | The page or post editor, Settings → Advanced, Head HTML field under Additional code snippets. |
| Shopify | An seo.hidden metafield (namespace seo, key hidden, integer value 1) adds noindex and nofollow and drops the page from the sitemap; a theme or app can also print a robots meta tag. |
Menu paths checked against each platform’s documentation on 30 October 2026.
Worked example: removing a tag leaves a header
This is an illustrative diagnosis, not a client result.
A public service page initially returns:
HTTP/1.1 200 OK
Content-Type: text/html
X-Robots-Tag: noindex
Its template also contains a noindex meta tag. The owner removes the template tag, but the host still adds the header. Adding <meta name="robots" content="index"> would not cancel the remaining noindex.
The actual correction is to remove the accidental production header rule for the intended page scope, while preserving exclusions that belong elsewhere. Verify the result on the affected service page and on a page that should remain excluded.
That second check matters. A global “remove every noindex” operation can solve the service page’s problem while exposing previews or transaction pages to indexing.
Do not use robots.txt to hide the instruction
A robots.txt block restricts crawling. It does not replace noindex, and it can prevent Google from seeing a new or removed noindex instruction.
For a public page intended for indexing, review both the page-level directives and crawl access. For a page intentionally excluded by noindex, Google normally needs access to read that rule. For a private page, use authentication or another appropriate access restriction rather than depending on search exclusion.
If your real goal is to choose one representative of duplicate content, read canonical tags explained before adding noindex. Canonical preference and exclusion have different outcomes.
Verify the correction at three levels
- Output: the accidental instruction is absent from all applicable HTML and response headers, and the intended content is publicly available.
- Google’s live test: the current fetched page no longer shows that blocker. Preserve the result and date.
- A later indexed record: after Google recrawls and processes the URL, inspect the recorded state again. Use Request indexing for an important corrected page where appropriate, then compare the next crawl with your release date.
If the next recorded reason changes to a duplicate or a crawled-but-not-indexed state, investigate that new evidence. Removing noindex removes one barrier; it does not establish that every other indexing condition has been satisfied.
Keep intentionally excluded URLs documented. For a broader visibility problem, use the website-not-showing decision tree, which separates discovery, indexing, rankings and Maps.
Google and WordPress documentation and the linked checker’s capabilities reviewed on 29 October 2026; plugin and platform settings checked on 30 October 2026.
Frequently asked questions
Is Excluded by noindex tag always a problem?
No. A page you deliberately keep out of search can correctly have this status. Investigate when an important public page should be eligible for search but Google recorded a noindex instruction.
Can noindex come from an HTTP header?
Yes. It can appear in a robots or Googlebot meta tag, or an X-Robots-Tag response header. Check all applicable sources. Adding index to HTML does not cancel a noindex instruction that still applies elsewhere.
Why does Search Console still report noindex after I removed it?
The indexed view may describe a crawl before your correction, another applicable directive may remain, or a cached response may still contain it. Compare the last crawl and release dates, inspect the public headers and HTML, and test the live URL in Search Console.
Search Console says noindex but I can't find the tag. Where is it?
Check the X-Robots-Tag HTTP response header first, then the rendered HTML, because JavaScript or a plugin can add the tag after the source you viewed. URL Inspection's live test and View tested page show what Google receives now; if they are clean, the report may describe a crawl from before your change.
Where do Squarespace, HubSpot and Shopify set noindex?
Squarespace uses the page's SEO tab (Hide page from search results) or page header code injection. HubSpot uses the Head HTML field under the page's Settings, Advanced. Shopify uses an seo.hidden metafield set to 1, or a robots meta tag added in the theme.