Google Index Checker: Indexability Pre-check
Last updated: What’s new
Test a URL’s live technical indexability signals. This tool cannot see Google’s index; use Search Console URL Inspection for the indexed status Google has recorded.
No signup required. Technical scan results may be used to produce aggregate website statistics. Research records do not include your name, email, IP address, or analytics ID. Privacy details
Live technical pre-check only: no Google index or Search Console data is queried. Pick a status to get it explained against the live evidence.
Referral reward
Know a business that needs a website or SEO?
Introduce them and earn a referral reward. They work with us directly, and we handle the proposal, delivery and support.
Know a business that needs a website or SEO?
Introduce them and earn a referral reward. They work with us directly, and we handle the proposal, delivery and support.
Projects: 10%, at least $100
Monthly services: 10% for the first six months
A $1,999 website earns you about $200. A $999 a month SEO plan earns about $600 over six months.
Your introduction message
This reference credits the introduction to you:
Email me the referral details
More options Send us this result or get a copy by email
What This URL Indexability Test Checks
The checker fetches one public URL as a diagnostic client and separates confirmed evidence from anything it could not determine:
- Redirect and response evidence: records each redirect hop up to the displayed limit, the final URL, final HTTP status, and content type.
- Googlebot directives: combines every generic robots meta tag, Googlebot-specific meta tag, and applicable X-Robots-Tag header.
- Robots.txt: evaluates the final path against Googlebot rules, including Allow, Disallow, wildcard, end-anchor, and longest-match precedence.
- Canonical target: reports the declared canonical and, for a different target on the same host, performs a bounded response, noindex, and robots check.
- Sitemap reference: checks advertised same-host sitemaps, or the conventional root sitemap when none is advertised, within strict document and size limits.
The fetch does not render JavaScript, imitate Google’s complete systems, assess content quality, or read Google’s index. Google’s URL Inspection documentation explains the difference between its indexed view and live test.
Technical Indexability Is One Gate, Not the Index
A crawlable 2xx URL without noindex can still be absent from Google, so use this result as a focused diagnostic:
- Response and directives are observable: the tool can show what this server-side fetch received now, including scoped Googlebot directives.
- Canonicalization is selected by Google: redirects and rel=canonical are strong preference signals, but neither proves which URL Google selected or indexed.
- Sitemaps help discovery: inclusion can support discovery and canonical consistency, but Google explicitly describes sitemap submission as a hint rather than a guarantee.
- Unknown stays unknown: a timeout, inaccessible robots.txt, cross-host canonical, oversized response, or sitemap limit is not displayed as a pass.
For the underlying rules, see Google’s documentation for robots meta and X-Robots-Tag, canonical signals, and sitemap guidance.
How to Diagnose “Google Is Not Indexing My Site”
Start with the exact affected URL, not an estimated domain-wide index count:
- Fix a non-2xx final response, redirect loop, or unintended redirect destination before interpreting page-level tags.
- Remove an unintended noindex from generic robots, Googlebot meta, or X-Robots-Tag. If robots.txt blocks crawling, Google may be unable to see a page-level noindex.
- Review a cross-canonical in context. Point it to the preferred duplicate only; do not assume every different canonical is an error.
- Keep preferred canonical URLs discoverable through internal links and, where appropriate, an XML sitemap. Missing sitemap inclusion alone does not prevent indexing.
- Inspect the exact URL in Search Console. Review the indexed status and Google-selected canonical, then run Test live URL after a fix and request indexing when appropriate.
A Google site: search is not exhaustive. Use it only as a secondary clue, never as the deciding index-status test.
When Search Console already names a status
Pick the status above the URL field and the result reads the live checks against it: Expected when the live page explains the status and nothing is wrong, Needs action when the live evidence shows something to fix, and Can’t tell from outside when the answer sits in Google’s own data, such as its crawl history or the canonical it selected.
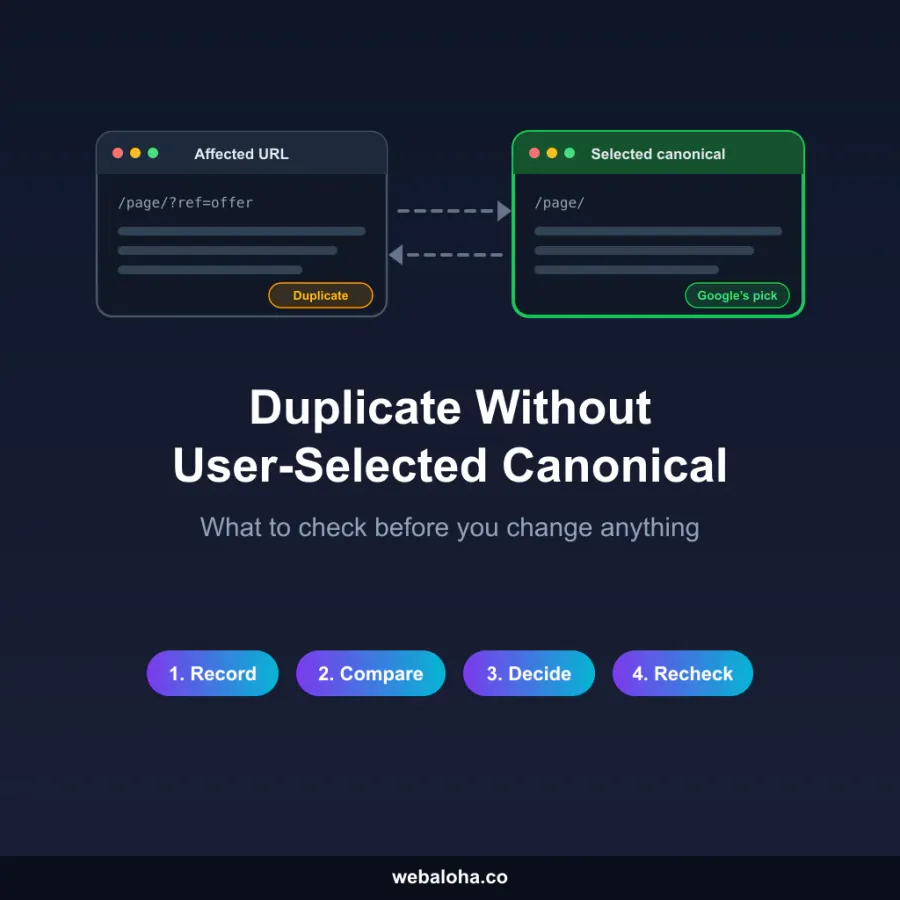
- Duplicate without user-selected canonical, Duplicate, Google chose different canonical than user and Alternate page with proper canonical tag: the declared canonical, its target and any redirect. Read duplicate without user-selected canonical: what to check before changing either URL.
- Crawled - currently not indexed and Discovered - currently not indexed: checks the selected live signals, without establishing why Google has not indexed the URL. Follow the crawled and discovered workflow in our Search Console guide.
- Page with redirect, Excluded by ‘noindex’ tag, Soft 404 and Blocked by robots.txt: the redirect chain, Googlebot directives, response and title, and the Googlebot robots.txt rules.
Example: HTTP 200, self-canonical and in the sitemap, but still not indexed
Those observations can coexist. Record the last crawl date in URL Inspection, compare its crawled HTML with the current page, and use Test live URL to review the rendered content and resources. This checker does not run that rendering test. Then inspect any similar page and the links that help users reach this URL.
A recorded “Crawled - currently not indexed” status alone does not prove a broken canonical, technical failure or particular content-quality problem. Correct an evidenced issue, request indexing when appropriate, and wait for a new crawl before judging the change. Changing the URL or repeatedly resubmitting it does not establish a fix.
Live Technical Checks Versus Google’s Indexed View
| Question | This live pre-check | Search Console URL Inspection |
|---|---|---|
| Which URL? | The entered public URL and checked final destination | The exact URL in a verified property, with Google’s canonical information |
| When was it observed? | At this fetch, subject to response caching | Indexed evidence from Google’s last recorded crawl; Test live URL is a separate current fetch |
| What can it answer? | Whether the tested response has selected technical blockers | Whether Google reports the URL indexed and the reason it records |
| What next? | Investigate returned blockers and unknown checks | Compare indexed and live evidence, then request indexing only when appropriate |
A passing live test does not guarantee indexing. Follow the Search Console guide to inspect the recorded URL.
What’s new
-
Interrupted compressed responses now finish with an explicit outcome instead of leaving the check waiting.
-
New: pick the Search Console status you see, such as a duplicate canonical or crawled but not indexed, and the result says if the live page explains it, what to fix, or that only URL Inspection can tell.
-
Only an HTTP 200 page counts as clean. A robots.txt that blocks every crawler is reported as unknown, and repeated identical canonical tags are no longer flagged.
Next steps
Google Index Checker: Indexability Pre-check related tools and articles
Continue with the closest follow-up checks and guides based on this tool's topic, crawl intent, and optimization workflow.