“AI visibility tool” (also sold as an LLM visibility tool or AI search monitoring) is a label for at least four different products. Some check whether AI crawlers can reach and read your pages. Some ask a language model to guess whether you would be recommended. Some run real prompts and record the answers. The paid ones repeat that over time and compare you with competitors. A tool can be good at one of these jobs and silent on the others.

We tested free tools on our own brand, Web Aloha (webaloha.co), on 26 September and 28 October 2026. The October tests below add answer-based tools and preserve the original September study separately. These are small dated samples, with no account, email or payment. Use them to choose an evidence type; the dates are separate snapshots.
Choose the tool by the evidence you need
| Your task | Useful evidence | Starting point |
|---|---|---|
| Check crawler rules, indexability and readable page content | Exact technical findings you can recheck | A readiness checker such as our AI Search Visibility Checker; access may require a bot check |
| Inspect a generated answer and its sources for your question | Answer text, cited URLs, collection mode and a date | The October Rank.ai and CitedSpy observations below |
| Verify what a buyer sees in a particular assistant | A saved answer from that consumer interface, with its mode and account state | Run a fixed manual prompt panel using the downloadable log |
| Compare repeated runs or competitors | The same prompts, surfaces and conditions over time | Ask a monitoring vendor for raw answers, failed-run handling, exports and its sampling method before paying |
AI visibility tracking tools: prices and engines
Paid AI visibility tracking tools run a fixed set of prompts on a schedule, save the answers and report brand mentions, cited URLs and share of voice against competitors. We have not tested any of them: each needs an account, an email or payment. The table lists what each vendor publishes on its own pricing page, checked on 30 October 2026. Prices are per month on monthly billing in US dollars; some vendors show euro or pound prices to European visitors.
| Tool | Engines covered (vendor’s list) | Prompts | Listed price | Our status |
|---|---|---|---|---|
| Otterly.AI | ChatGPT, Google AI Overviews, Perplexity, Copilot; AI Mode, Gemini and Claude as paid add-ons | Lite 15, Standard 100, Premium 400 | Lite $29, Standard $189, Premium $489 | Not tested: account needed (free trial) |
| Peec AI | 3 of ChatGPT, AI Mode, AI Overviews, Copilot, Gemini and Naver AI; Perplexity and Claude on Enterprise | Starter 50, Pro 150, Advanced 350, daily | Starter $95 (€85), Pro $245 (€205), Advanced $495 (€425) | Not tested: account needed |
| Semrush AI Visibility Toolkit | ChatGPT, Google AI, Gemini and Perplexity | 25, daily | $99 per domain (Semrush help centre) | Not tested: the free checker rejected our request as suspicious in September |
| Ahrefs Brand Radar | AI Overviews, AI Mode, ChatGPT, Perplexity, Gemini, Copilot; Claude for custom prompts | Index of 519 million prompts, plus your own custom prompts | AI Visibility Index from $199, custom prompts from $50 | Not tested: the free checker showed a bot check in September |
| Rankscale | ChatGPT, Perplexity, AI Mode, AI Overviews, Gemini, Claude, Copilot, DeepSeek, Mistral | Credits: 1,200 a month on Pro | Pro $99, Pro+ $229 | Not tested: account needed |
| Profound | Trial: ChatGPT, Gemini, AI Overviews. Enterprise: up to 9 engines | Trial: 50 prompts daily for 7 days | Free trial; Enterprise on request | Not tested: account needed for the trial |
| Am I On AI | ChatGPT and Google AI Overview | Pro 150, Prism 750 | Pro $100, Prism $349, GEO Council $2,500 (waitlist) | Not tested: the free audit asks for an email |
The cheapest way in is Otterly.AI’s Lite plan at $29 for 15 prompts, enough for a small fixed panel on four engines. Peec AI and Semrush suit a 25 to 50 prompt panel, and Ahrefs’ index suits brands that already appear in AI answers and want competitor data without writing prompts. The prices are what each vendor states; we have not verified how any of them collects answers, so ask the questions below before you pay.
A person in a normal browser may not see the Ahrefs and Semrush bot checks, so their free checkers are worth trying yourself. We also tried Authority Radar’s free check, which asked for an email before showing anything.
October update: what the public tools actually returned
We fixed two unbranded questions before running them, using questions from our existing prompt panel:
- Agency question: “Which agencies can migrate a small service-business website from WordPress to Astro while preserving URLs and SEO? Show evidence for your suggestions.”
- Evidence question: “Show documented WordPress-to-Astro migrations with before-and-after performance measurements and explain the test conditions.”
We submitted both questions to each tool, then repeated the agency question once to inspect caching. Rank.ai also received our public brand name and domain in its matching fields; CitedSpy asked only for the query. Those different inputs mean this is a method comparison, not a controlled platform ranking.
Conditions: 28 October 2026, approximately 15:05 to 15:12 UTC; Playwright CLI with headless Chromium, isolated logged-out sessions, browser language en-US. A client-side network check returned GB; neither tool disclosed its answer-generation location. We saved the rendered results, response data and screenshots. We did not rerun September’s direct consumer-platform panel, create an account, submit an email, buy a plan or bypass a challenge.
| Public tool | Agency question | Evidence question | What we could verify |
|---|---|---|---|
| Rank.ai AI visibility checker | Gemini-labelled result listed our migration service as citation 2. ChatGPT- and Claude-labelled cards showed zeroes with blank answer previews | ChatGPT-labelled preview was blank; Claude-labelled preview only said it would retrieve the sources; Gemini-labelled result failed | A returned citation list and a short excerpt, with incomplete answer evidence for other cards. Blank previews cannot verify the negative verdicts |
| CitedSpy AI Search Citation Checker | Two of three enabled engines responded: Gemini and Google AI Mode. Neither returned citation list included our domain | The same two responded and both lists included our migration-results article. ChatGPT was marked not reached | Returned excerpts and linked citations; no successful ChatGPT answer. Perplexity and Copilot were not enabled in the public response despite the five-engine landing copy |
| Web Aloha AI Search Visibility Checker | Homepage URL submitted instead of a prompt, because this is a readiness tool | Not applicable | A security-check gate appeared before a result. We stopped there and recorded no October readiness score |
The two owned citation URLs returned HTTP 200 when checked: our migration service and migration results. We inspected the vendors’ returned evidence; their upstream requests and equivalence to consumer interfaces remain unverified.
Rank.ai: useful citations, incomplete answer evidence
Rank.ai discloses API access and its own Google-results search tool. Its FAQ named older model versions than the run response reported. We therefore retained the response’s model identifiers as vendor-reported metadata rather than claiming we authenticated provider versions.
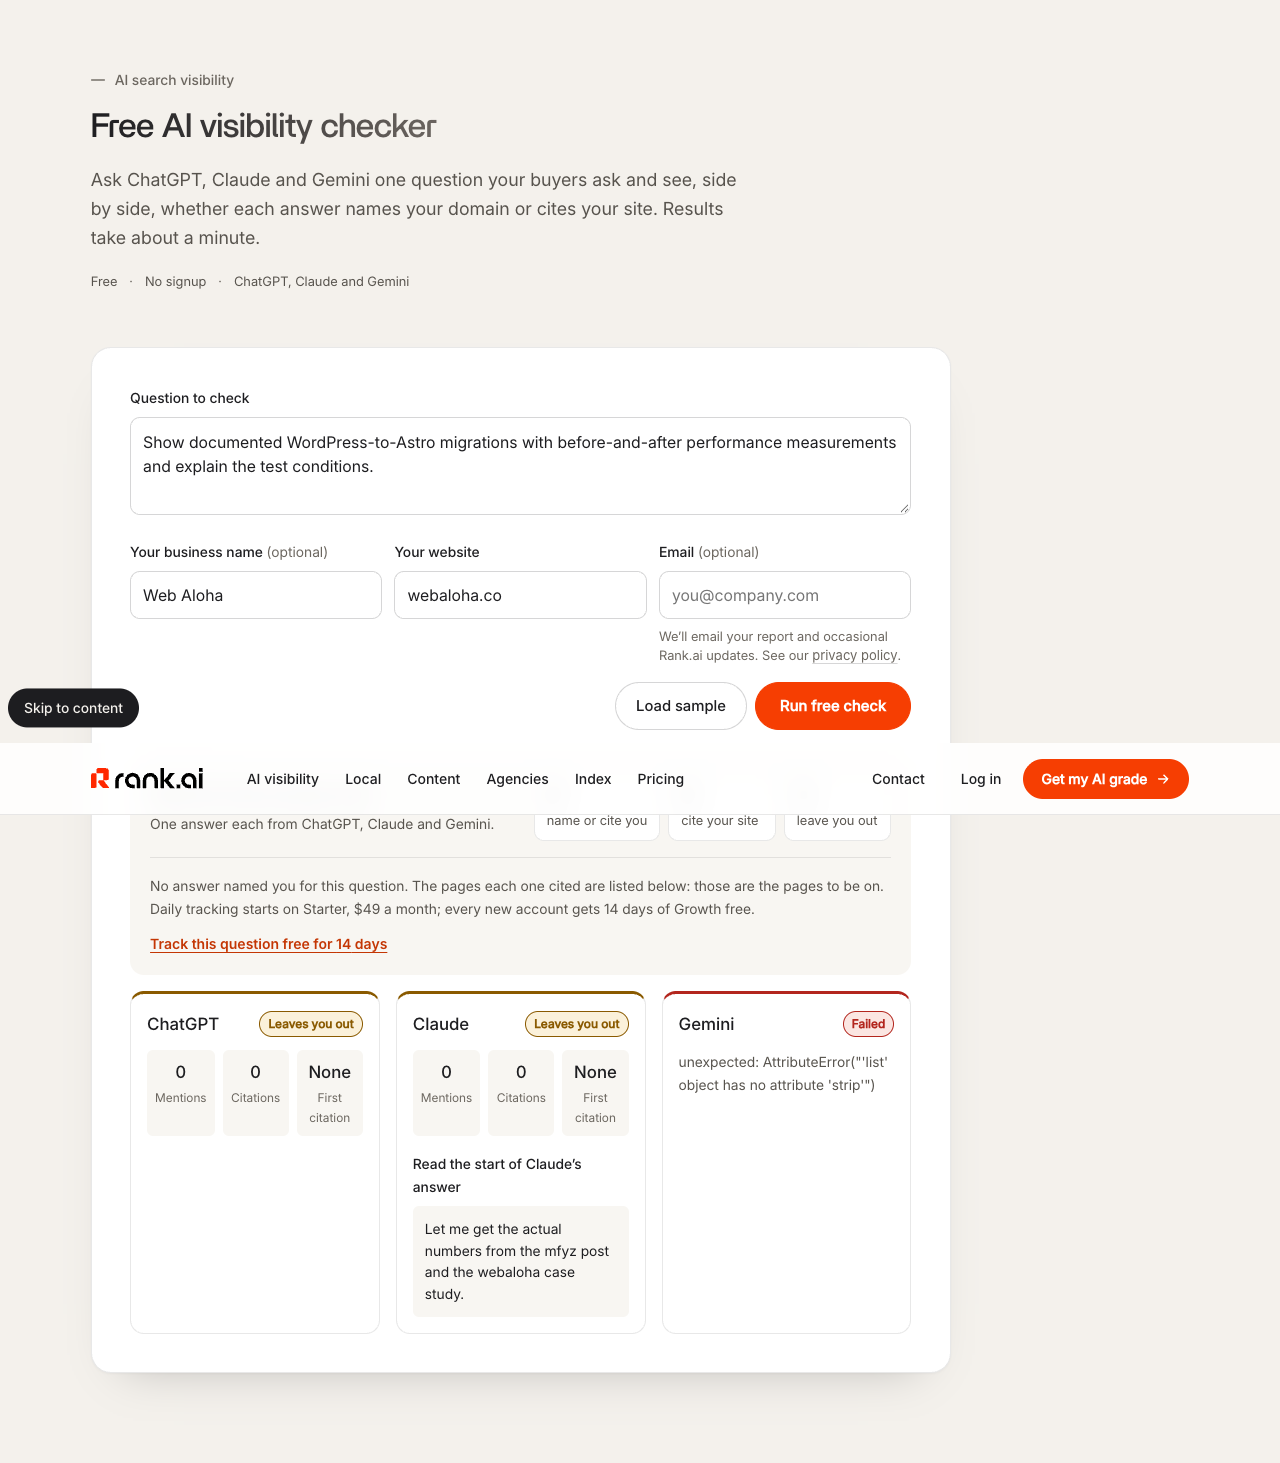
The agency question produced a Gemini-labelled excerpt and four cited pages, including ours. The other two previews were empty despite “leaves you out” verdicts. The evidence question exposed a clearer contradiction: the Claude-labelled card reported zero mentions, yet its returned excerpt explicitly named webaloha while describing sources it intended to retrieve. It reported zero citations and supplied no linked sources for that excerpt. The score and visible text disagreed about a mention; the text was still not a completed, inspectable answer. Gemini failed on that question. We would record those incomplete cards as unavailable evidence, not verified brand absence.
The first-question repeat explicitly returned a cached result. The published cache interval was six hours, with five checks per network per hour. A repeat inside that window tests cache behavior, not answer stability. The source-list position also describes the first citation’s position, not a brand’s ranking inside an answer.
View our actual Rank.ai evidence-question capture, 28 October 2026. The failed Gemini card and incomplete answer evidence are visible in the capture.
CitedSpy: linked sources, narrower engine coverage
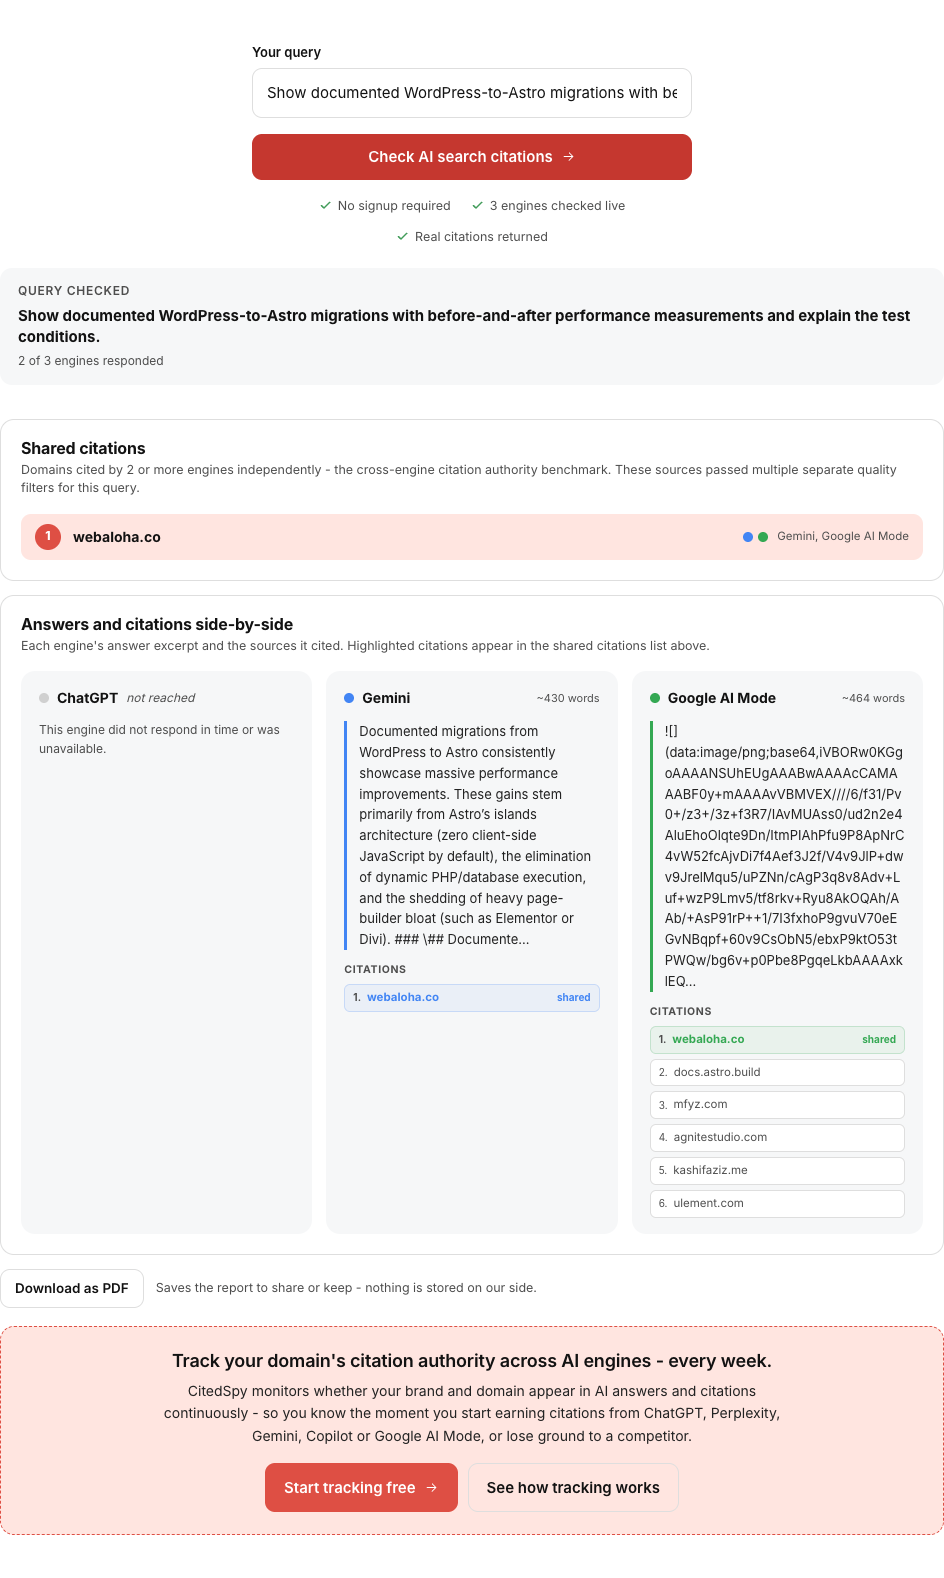
CitedSpy’s checker returned answer excerpts and linked sources without an email. Its enabled-engine response listed ChatGPT, Gemini and Google AI Mode. Both questions returned the latter two; ChatGPT remained unavailable. The evidence question’s two returned citation lists both included our published migration-results article.
The report showed short excerpts, not full inspectable answers. Its Google AI Mode excerpts also contained image-markup text. We could inspect citation targets but could not verify its upstream collection route, exact model, location or equivalence to the consumer interfaces. The result displayed a PDF button; we did not test its export.
The first-question repeat carried a cache flag and the same answer data. CitedSpy states a 24-hour cache. Its “shared citations” label is a vendor summary of these returned lists, not an independently established authority score.
View our actual CitedSpy evidence-question capture, 28 October 2026. It shows two responding engines, the unavailable ChatGPT card and the returned citation lists.
What changed since September
The original finding below remains a statement about eight selected tools on 26 September. It should not be read as “no free tool can show an answer today.” October’s two additions returned excerpts and citations, while exposing missing engines, incomplete previews and cache reuse.
For a business owner, the useful next step is to save the answer evidence behind a score. Keep unavailable engines outside a citation-rate denominator, and report how much of the planned panel actually completed. Use the measurement guide and reporting templates for that workflow.
Original study: 26 September 2026
The following results and scorecard describe the original test date. October’s tests cover only the tools listed above. The paid trackers we could not test are listed, with prices re-checked on 30 October 2026, in the prices and engines section. We tried eight free tools under the September rules and five returned results.
The September short answer
| Your question | What answers it | What we saw on 26 September 2026 |
|---|---|---|
| Can AI crawlers reach and read my pages? | A readiness checker, such as our AI Search Visibility Checker or Answer Visibility Lab’s AI Crawlability Checker | Both scored webaloha.co 100, and every finding matched the live site |
| What does a model think of my brand? | A model-based checker: HubSpot AI Search Grader, Rank Prompt, SEOcrawl | Scores from 22 to 52 out of 100 and “likely not named” verdicts: opinions, not measurements |
| Do AI answers mention or cite me for my buyers’ questions? | Your own prompt panel, or a monitoring tool that shows the raw answers | Perplexity named us in 2 of 6 answers and ChatGPT in 1 of 6; none of our 4 discovery prompts named us |
| Is that improving, and how do we compare with competitors? | A paid monitoring tool with a published method | Not tested: every option needed an account, an email or payment |
The most useful finding: none of the free tools that returned a result showed us what an AI search answer to a buyer’s question actually says. Two checked technical readiness. Three were model-based: HubSpot asks each model how it describes the brand from its training data, while Rank Prompt and SEOcrawl ask one model to estimate whether you would be named, and both say so on the results page.
How we tested in September
We wrote the jobs, criteria and rules down before running anything, then applied them to every tool:
- Date: all runs on 26 September 2026, within about 30 minutes.
- Brand: Web Aloha,
webaloha.co, homepagehttps://webaloha.co/. - Browser: Playwright with headless Chromium, a fresh profile per tool, logged out, English (UK), connecting from Lithuania.
- Inputs: the homepage URL for readiness tools; “Web Aloha” or
webaloha.cofor brand tools. Where a tool asked for a business description we used “Worldwide”, “Web design and digital marketing” and “Web design, SEO and GEO for small businesses”. - Rules: no account, no email, no payment and no personal data. Non-essential cookies declined. A CAPTCHA, bot check or email gate ended the test for that tool, and we never bypassed one.
- Verification: we checked every claim against something outside the tool: the live
robots.txt, sitemap,llms.txtand page markup for readiness findings, and a same-day manual prompt panel for anything about mentions or citations. - Our own tool: its public page uses a Cloudflare bot check (Ahrefs and Semrush use similar protection), so under these rules it would have been blocked too. We ran the same code from a local build and called its API directly. Judge its results with that in mind.
We scored each tool we ran from 0 to 2 on five criteria: method transparency, verifiable results, fit for its job, honest claims and actionable advice. The scorecard is further down.
September readiness checks: can AI crawlers reach and read your pages?
Readiness is the one job a free tool can do completely, because it is deterministic: fetch the page and robots.txt, apply the rules, parse the markup. Two tools ran cleanly.
Web Aloha AI Search Visibility Checker (free, no account). Our tool scored the homepage 100 out of 100: all 8 scored checks passed (page status, HTTPS, access for OAI-SearchBot, Claude-SearchBot, PerplexityBot and Googlebot, no noindex, language, H1 and title). It also listed 15 unscored observations, including 4 JSON-LD blocks that parsed (Organization, WebSite, WebPage, ItemList) and about 940 words of text in the server-returned HTML. We checked the crawler rules and schema types against the live site, and they matched. One honest caveat: the name says “visibility”, but it measures readiness. It does not run prompts or track citations, and the tool page says so next to the input.
Answer Visibility Lab AI Crawlability Checker (free, no account). It also scored the site 100 (“AI crawl-ready”). It covers a different slice: robots.txt, the Sitemap directive, sitemap.xml, llms.txt, a homepage noindex check, and a matrix of eight crawlers (including GPTBot, OAI-SearchBot, ClaudeBot, PerplexityBot, Googlebot and Bingbot) across priority paths. Every finding matched the live files, and it states under the score that it does not guarantee citations or recommendations.
The two overlap on crawler access and differ elsewhere. Answer Visibility Lab checks site files such as sitemap.xml and llms.txt. Ours checks the page itself (structured data, server-rendered text, headings and indexing headers) and reports user-triggered fetchers such as ChatGPT-User separately, without scoring them. Use either or both. Just don’t read 100 as “AI search recommends us”: the next two sections show why.
September model-based checkers: what a model thinks of you
These tools don’t observe AI search answers. They ask a language model about your brand, or ask it to predict whether you would be named. That can prompt useful reflection, but it is not a measurement of AI search.
HubSpot AI Search Grader (free; the full report needs an email). We entered the company name, “Worldwide”, the industry and the services. Without an email it showed three scores out of 100: OpenAI 32, Perplexity 52 and Gemini 37, each split into brand recognition, market score, presence quality, sentiment and share of voice. HubSpot says the grader asks each model how it characterises the brand based on its training data. The answers behind the scores are only in the full report, which asks for an email, so we could not check any of them. A second run with identical inputs gave identical scores. That fits HubSpot’s “deterministic scoring” claim, although we can’t tell whether it re-ran or served a stored result.
Rank Prompt free checker (free, no account). With our brand, the closest industry option (“Marketing Agency”) and our category, it returned “0 of 3 assistants would likely name your brand” for ChatGPT, Perplexity and Gemini, each with a one-line reason. Directly under the result it says the verdicts were estimated by an OpenAI model, not live answers from each assistant. That was the clearest disclosure we saw. The question it estimated for is not shown, so there is nothing to re-check.
SEOcrawl AI Visibility Checker (free, no account). It scored us 22 out of 100 (“Poor”), said all four engines “rarely” name us, suggested nine prompts and a six-step plan, and named six “competitors” that it said are surfacing in AI answers for prompts where we should appear. The brand facts it listed were accurate: 94 free tools, 8 countries and a result from one of our case studies. But the competitor claim reads as an observation, while the report’s own footer calls it an AI-generated estimate, not a live measurement. None of those six agencies appeared in any of the 12 answers from our same-day prompt panel. Our prompts were different, so that doesn’t disprove the claim, but nothing supports it either. One of its three high-priority actions asks for an llms.txt file and Organization schema, and both were already live on our site. It also published the report at a public (noindexed) URL.
The pattern across all three: plausible, broadly fair for a small agency, and impossible to verify. Treat them like asking one well-read person for their impression.
September observed answers: what AI search actually said
The only way to know what an AI answer says is to look at it. On the same day we ran our fixed six-prompt panel, the method described in our guide to measuring GEO and AI visibility, in a fresh, logged-out browser from Lithuania:
| Platform | Answers recorded | Web Aloha named |
|---|---|---|
| Perplexity (web search) | 6 of 6 | 2: our branded question, and an unbranded request for documented WordPress-to-Astro migrations, where it listed our published Gridinta migration evidence first, with webaloha.co as the source |
| ChatGPT (search, logged out) | 6 of 6 | 1: our branded question |
| Google AI Mode | 0 of 6 | Not measured: Google showed our automated browser a bot check |
None of the four discovery prompts (two agency recommendations, a font tool and an internal-link tool) named us on either platform. So the estimates were broadly right about generic “which agency” questions. What they could not see is the one thing that did work: a specific, evidence-seeking question, answered with our published migration evidence. That is the difference between a guess and an observation, and it is why a readiness score of 100 and an estimate of 22 can both be “true” without telling you what to do next.
Twelve answers on one day are a snapshot, not a trend. Answers vary between runs, locations and accounts, so repeat the same prompts on a schedule before drawing conclusions.
September scorecard for the tools we ran
Each criterion is scored 0 to 2. The scores rate how well a tool does the job it claims and how honestly it presents its results. They are not a ranking: a readiness checker scores well on transparency because readiness is easy to verify, but it cannot tell you whether AI answers mention you.
| Tool | Job | Scores (0 to 2) |
|---|---|---|
| Web Aloha AI Search Visibility Checker | Readiness | Method 2, verifiable 2, fit 2, honest 1, actionable 2 |
| Answer Visibility Lab AI Crawlability Checker | Readiness | Method 2, verifiable 2, fit 2, honest 2, actionable 2 |
| HubSpot AI Search Grader | Model perception | Method 1, verifiable 0, fit 1, honest 1, actionable 0 |
| Rank Prompt free checker | Model estimate | Method 1, verifiable 0, fit 1, honest 2, actionable 0 |
| SEOcrawl AI Visibility Checker | Model estimate | Method 1, verifiable 1, fit 1, honest 0, actionable 1 |
The scores that need explaining:
- Our own checker loses a point on honesty. Its name says “visibility” while it measures readiness. The scope note sits next to the input, but the name alone can mislead.
- Rank Prompt gets full marks on honesty for stating, directly under the verdict, that it was estimated by an OpenAI model and is not a live answer.
- SEOcrawl scores 0 on honesty because its headline presents an estimate as an observed fact, with urgency copy. The notes calling it an estimate come further down the report.
- HubSpot scores 0 on verifiability because the answers behind its scores are only in the emailed report.
Questions to ask before you pay for monitoring
Monitoring vendors use different collection methods. Before you pay, ask:
- Which prompts? Can I write my own and see the exact wording?
- Which platforms and modes (ChatGPT with or without search, AI Overviews, AI Mode, Perplexity), logged in or out, and from which country?
- Can I see the raw answer and the cited URLs behind every number?
- How often is each prompt re-run, and how are answers that change between runs counted?
- How is share of voice calculated, and which competitors are included?
- Can I export the data?
If a vendor can’t answer these, its dashboard is a score you can’t check.
What we would do for a small business
- Run a readiness check on your most important pages and fix anything that blocks crawlers or hides text. Our AI Search Visibility Checker is free. Treat the result as a foundation, not an outcome.
- Write 10 to 20 questions your buyers really ask, including a few specific, evidence-seeking ones about your work. Run them monthly on the platforms your customers use, logged out, and save the answers.
- Track AI referral visits and enquiries in analytics, separately from mentions.
- Pay for monitoring only when the manual panel gets too slow for the prompts, platforms or competitors you need, and choose a tool that shows its raw answers.
Our guide to measuring GEO and AI visibility has the full prompt-panel template. If you would rather hand the work over, our GEO services cover the technical fixes, citation-focused content and ongoing AI visibility monitoring.
Frequently asked questions
What is the best free AI search visibility tool?
Choose by the job. A readiness checker tests technical access and page structure. In our 28 October 2026 public tests, Rank.ai and CitedSpy returned answer excerpts and citation lists without an account, but both had incomplete or unavailable engine evidence. A fixed manual prompt panel remains useful when you need to verify the consumer interface itself.
Do free AI visibility checkers show real ChatGPT or Perplexity answers?
Some now show generated answer excerpts and citations, but check the collection method. Rank.ai says it uses model APIs and its own search tool, which does not reproduce consumer ChatGPT or Claude search. CitedSpy enabled three engines, received answers from two and marked ChatGPT not reached in both October questions. We did not verify its upstream collection method or a Perplexity answer.
Is an AI readiness score the same as AI visibility?
No. Two readiness checkers scored webaloha.co 100 on the same day that none of our four discovery prompts named us in ChatGPT or Perplexity. Readiness shows that crawlers can reach and read a page. Visibility depends on relevance, authority and the exact question.
What do AI visibility tools track?
Paid AI visibility tracking tools run a fixed set of prompts on a schedule and report brand mentions, cited URLs, sentiment and share of voice against competitors. Readiness checkers, such as ours, only check whether AI crawlers can reach and read your pages.
How much do AI visibility tracking tools cost?
On 30 October 2026 the vendors' pricing pages listed Otterly.AI from $29 a month for 15 prompts, Peec AI from $95 (€85 on its euro price list) for 50 prompts, Semrush's AI Visibility Toolkit at $99 and Ahrefs' AI Visibility Index from $199. Profound prices its enterprise plans on request.
Can I track AI visibility for free?
Partly. Free checkers such as Rank.ai and CitedSpy show one-off answer excerpts and citations, and a fixed monthly prompt log plus AI referral tracking in GA4 gives you a repeatable baseline at no cost. Our measurement guide includes a free prompt-log template.
Do I need a paid AI visibility monitoring tool?
Only when a manual prompt panel becomes too slow for the prompts, platforms or competitors you need to track. Before paying, ask to see the exact prompts, platforms, location, account state, raw answers and cited URLs behind every metric.
How did you test these tools?
The original 26 September 2026 study used our own brand in fresh logged-out browsers and included a separate manual prompt panel. On 28 October we added two fixed public questions in Rank.ai and CitedSpy, repeated the first once to check caching, and tried Web Aloha's public checker. We used no account, email or payment and stopped at its bot check. The October runs did not repeat the September consumer-platform panel.